Your data stays yours
Models run on your devices and your servers. Prompts, docs and customer records never go to OpenAI or any other AI provider. Compliance comes built in.
Private AI for companies
Your AI. Your infra. Your data stays home.
We help companies run AI on their own devices and servers, so nothing goes to OpenAI or anyone else. It’s faster, and you pay a fixed cost that’s 5–10× lower than per-token APIs.
The usual way to adopt AI: send your data to a frontier model and pay per token, forever. We run the models where your data already lives, on your users’ devices and your own backend. Private, faster, fixed-price.
Models run on your devices and your servers. Prompts, docs and customer records never go to OpenAI or any other AI provider. Compliance comes built in.
The model sits next to your data, on the edge or in your backend. No round-trip to someone else's API, no rate limits, no waiting behind their other customers.
Our compute primitives return a typed answer (a label, a field, a ranking) instead of a wall of text. For those jobs they beat frontier models by 10–50×.
We split the work between edge devices and your backend. No per-token billing: you pay a fixed amount, 5–10× below frontier APIs, and it stays flat as you grow.
Most business AI tasks don’t need a paragraph back. They need a label, a field, a ranking, a yes or no. Our compute primitives return exactly that, a typed value instead of a string, so they finish 10–50× faster than a frontier model writing it out.
classifyOne label from your list, or “unsure”extractA value for each field you define, pulled from the inputrankYour items, reordered. Nothing inventedrouteOne action from your set. An intent, never a side effectframeShort text derived from the input, length-cappedmatchGroups of duplicates and look-alikesdetectSpans that hit a category: PII, secrets, toxicityverifySupported, contradicted or unclear, against your evidencescoreA grade on your rubric, no made-up numberschooseThe single best option for a criterion, or “unsure”Each primitive is defined as data (a schema, parameters and test cases), so adding or tuning one for your business doesn’t mean rebuilding anything. More at computeprimitives.com ↗
New: Brink Cube
Don’t want to run servers? We’ll ship you an appliance built for AI agents. Plug it in, pair it from your phone, and your agents run on hardware you own, connected to the tools you already use.
Purpose-built hardware and software for running AI agents 24/7. Not a repurposed mini PC or a cloud VM.
Connect it to power and your network, scan to pair, and deploy your first agent from the app.
Local models run on the Cube. Need a bigger model for one task? Route it out under rules you set, and everything else stays local.
Set a budget for each agent, track every token that goes out, and get alerts before anything runs over.
GitHub, Slack, Gmail, Linear, Notion, Google Drive and more. Connect with a tap instead of setting up OAuth apps.
Give each agent its own email address and phone number, with 2FA, so it can handle support tickets and capture leads.
Watch agents work in real time, deploy new ones and see spend from your phone.
We split the workload between edge devices and your backend, so there’s no meter running per token. Your cost is fixed and 5–10× lower than frontier APIs, and it doesn’t move when usage takes off.
At 3× usage, the per-token bill is about 21× yours.
Illustrative. Your fixed price depends on the workload; we scope it with you up front.
| Compare | Frontier API | Brink |
|---|---|---|
| Where your data goes | A third-party AI provider | Your devices and servers |
| How you pay | Per token, metered | Fixed |
| Usage doubles | Your bill doubles | Your bill stays put |
| Core tasks | Writes text token by token | Typed answers, 10–50× faster |
Your users' phones, laptops and desktops
iOS, Android, macOS, Windows and Linux, GPU-accelerated on each
Your servers, on-prem or in your own cloud account, or a Brink Cube
Bigger models and shared workloads, inside your network
Our clients ship AI that runs on their users’ devices, with no prompts sent to anyone’s cloud.
The app’s AI assistant (chat, news summaries and market Q&A) runs fully on-device with Brink Compute. Instant answers, works offline, and no prompt ever touches a server.
Summarize today's Bitcoin headlines.
BTC is holding above support after ETF inflows ticked up. Two macro prints land this week, so watch for volatility.
Is this hitting a server?
Nope. I'm running locally on this device. Works in airplane mode too.
Records a conversation, transcribes it, works out who said what and writes the summary, with speech recognition and a language model running side by side on the phone, offline.
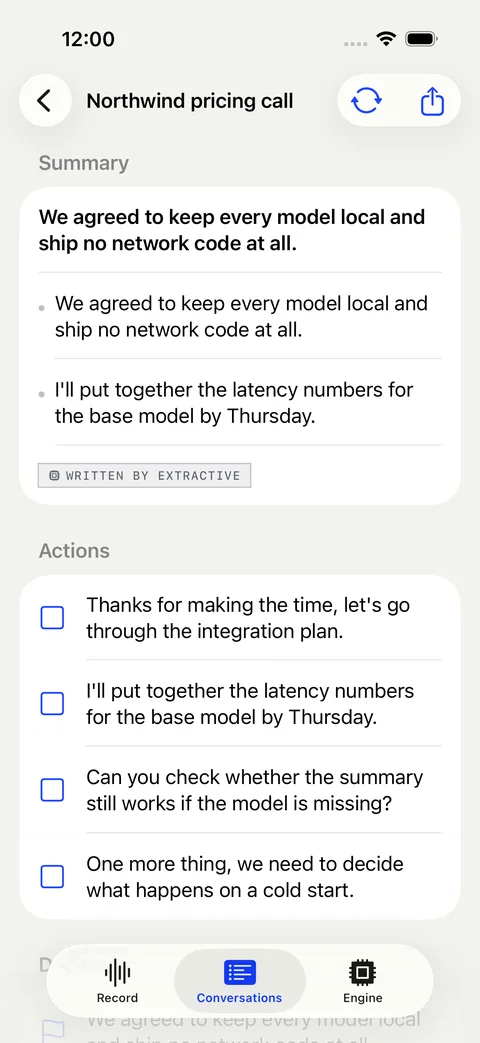
We find where AI pays off for you (support triage, doc extraction, search, compliance checks, assistants) and what each task actually needs to return.
Each task becomes a compute primitive or a local model, placed on your users' devices, your servers or a Brink Cube based on size, speed and how sensitive the data is.
You get AI that's private, fast and fixed-price. Your data never leaves your control, and your bill doesn't climb with usage.
Tell us what you want AI to do for your business. We’ll show you how to run it on your own infra, with your data staying put and a cost that doesn’t creep up.